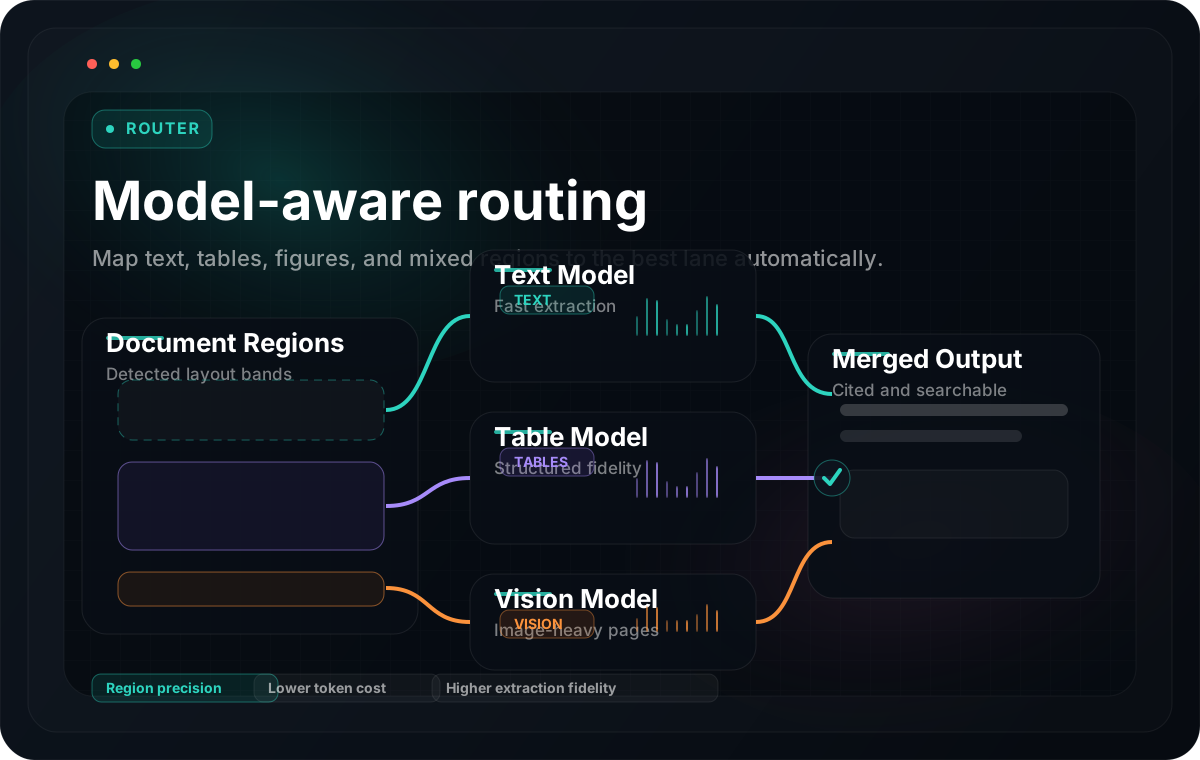
Dynamic LLM Routing
Auto-selects the optimal model per document region — text, tables, images, mixed content.
DocSlurp transforms any document into structured, searchable intelligence. Smart LLM routing, table extraction, image captioning, citations — all through one API.
import { createDocSlurpClient } from '@docslurp/sdk';
import { readFile } from 'node:fs/promises';

const client = createDocSlurpClient({
  apiUrl: process.env.DOCSLURP_URL!,
  apiKey: process.env.DOCSLURP_API_KEY,
});
const { workspace, run } = await client.upload({
  files: [{ filename: 'report.pdf',
    data: new Blob([await readFile('report.pdf')]) }],
});
await client.waitForRun(run.id);
const answer = await client.chat({
  workspaceId: workspace.id,
  q: 'What are the key findings?',
});From raw PDFs to structured, searchable intelligence — DocSlurp handles the entire pipeline.
Auto-selects the optimal model per document region — text, tables, images, mixed content.
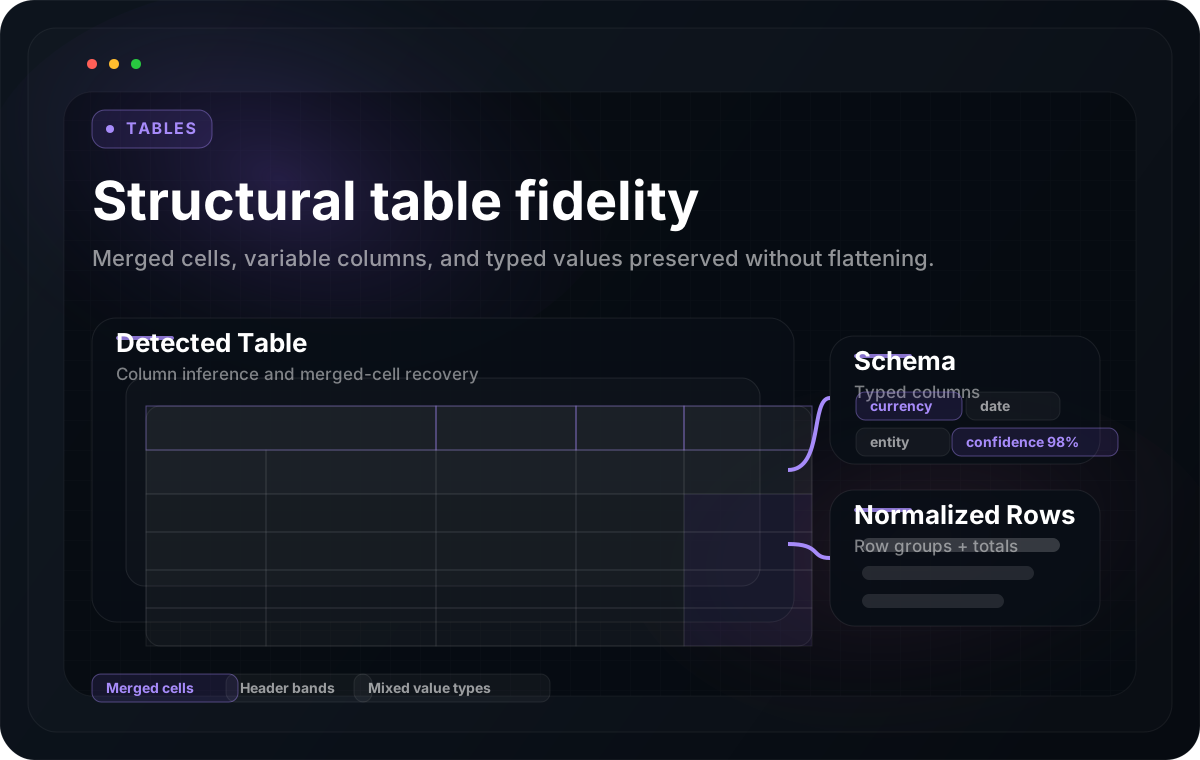
Variable columns, merged cells, mixed content types — all handled with structural fidelity.
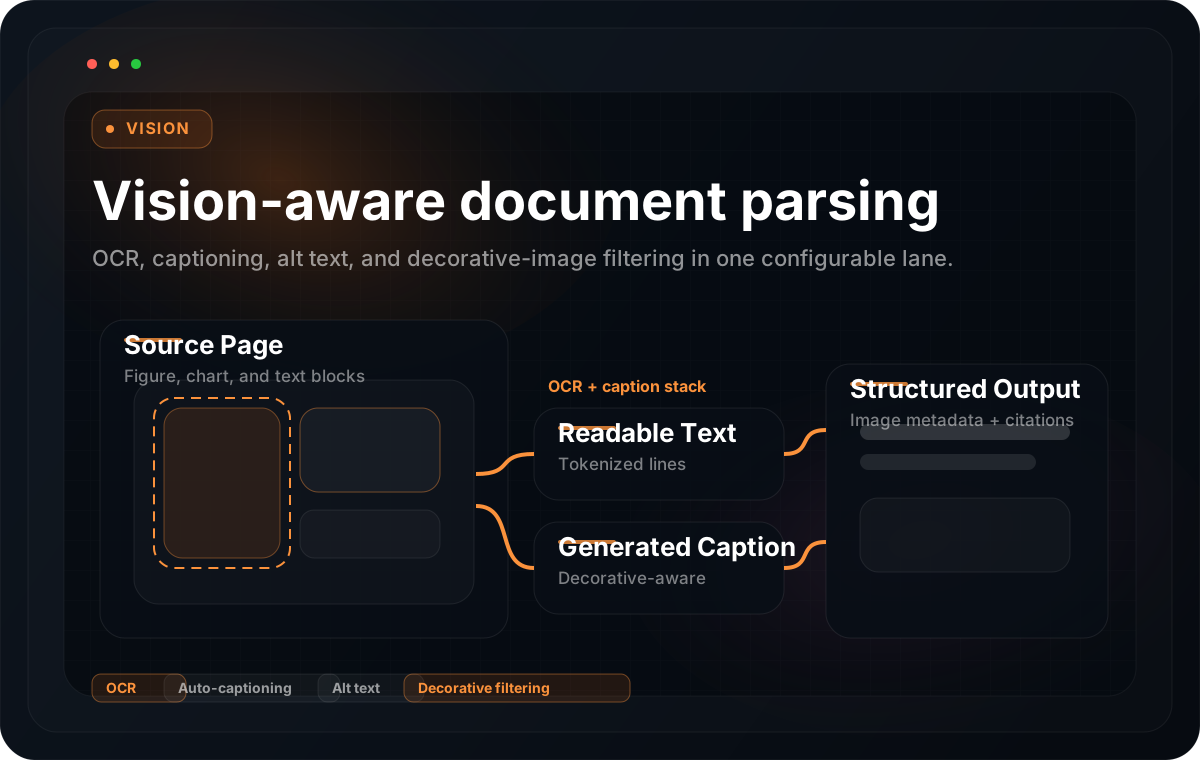
Turn document images into searchable context alongside extracted text.
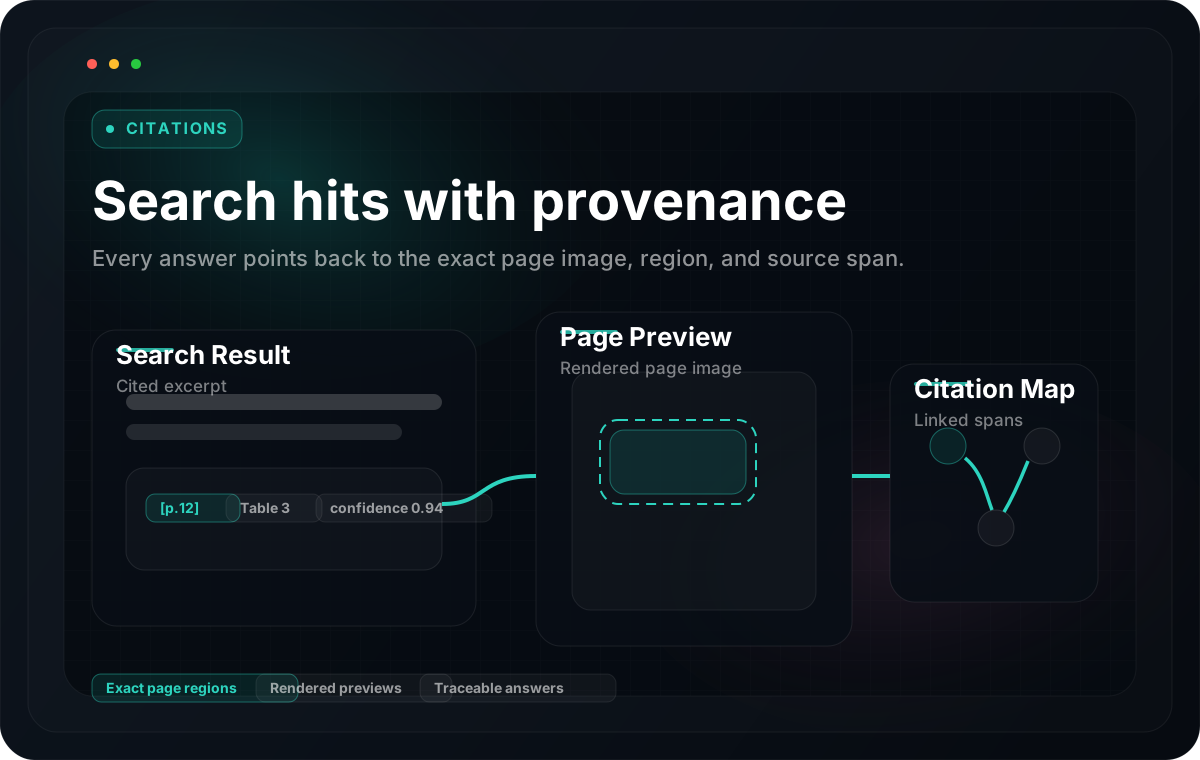
Every search result links back to exact page regions with rendered page image previews.
Identifies headers, footers, sidebars, figures, and body text with spatial precision.
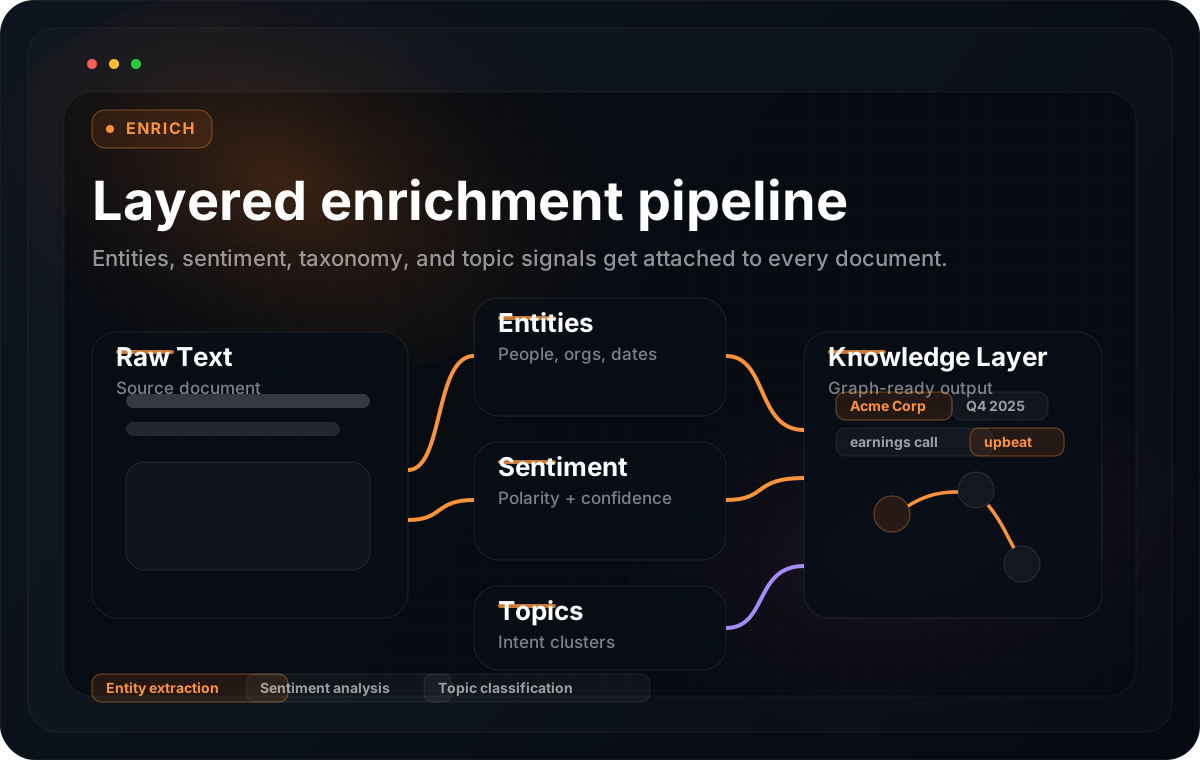
Entity extraction, sentiment analysis, topic classification — layered onto every document.
Dynamic, filterable word cloud visualizations for rapid corpus understanding.
Explore relationships between topics, entities, and document intent in interactive graphs.
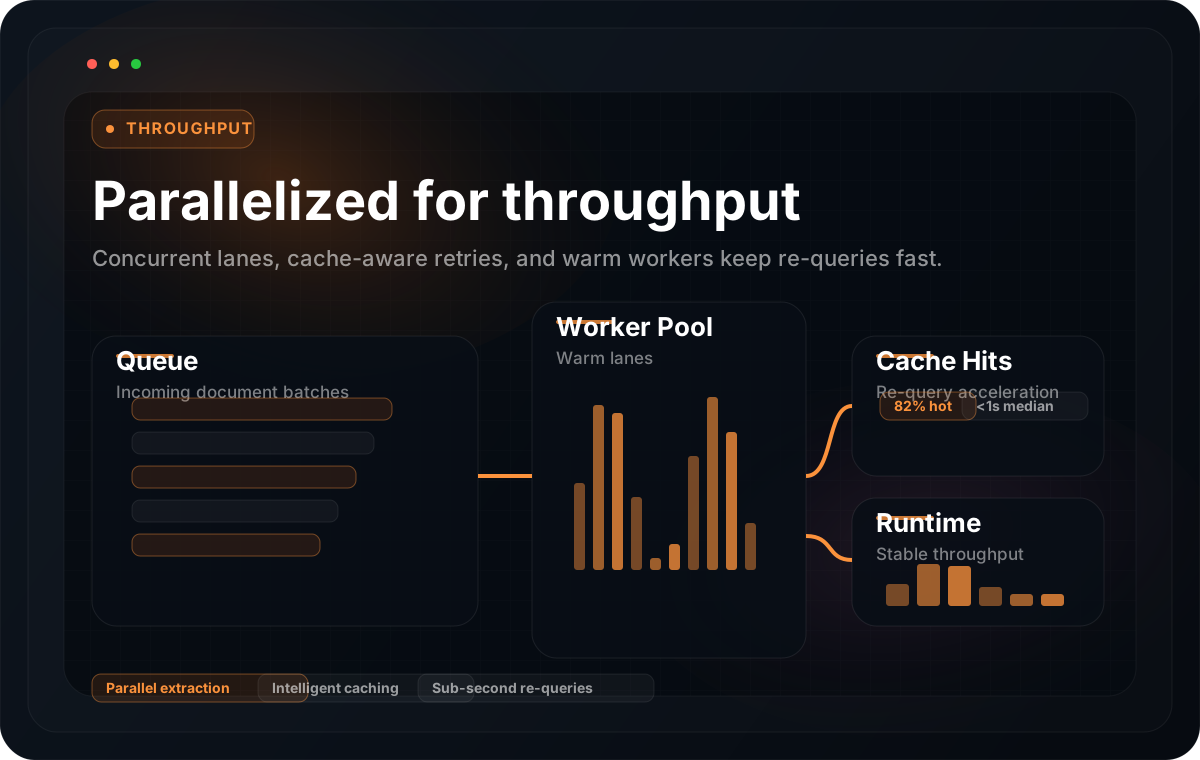
Parallel extraction pipelines with intelligent caching for sub-second re-queries.
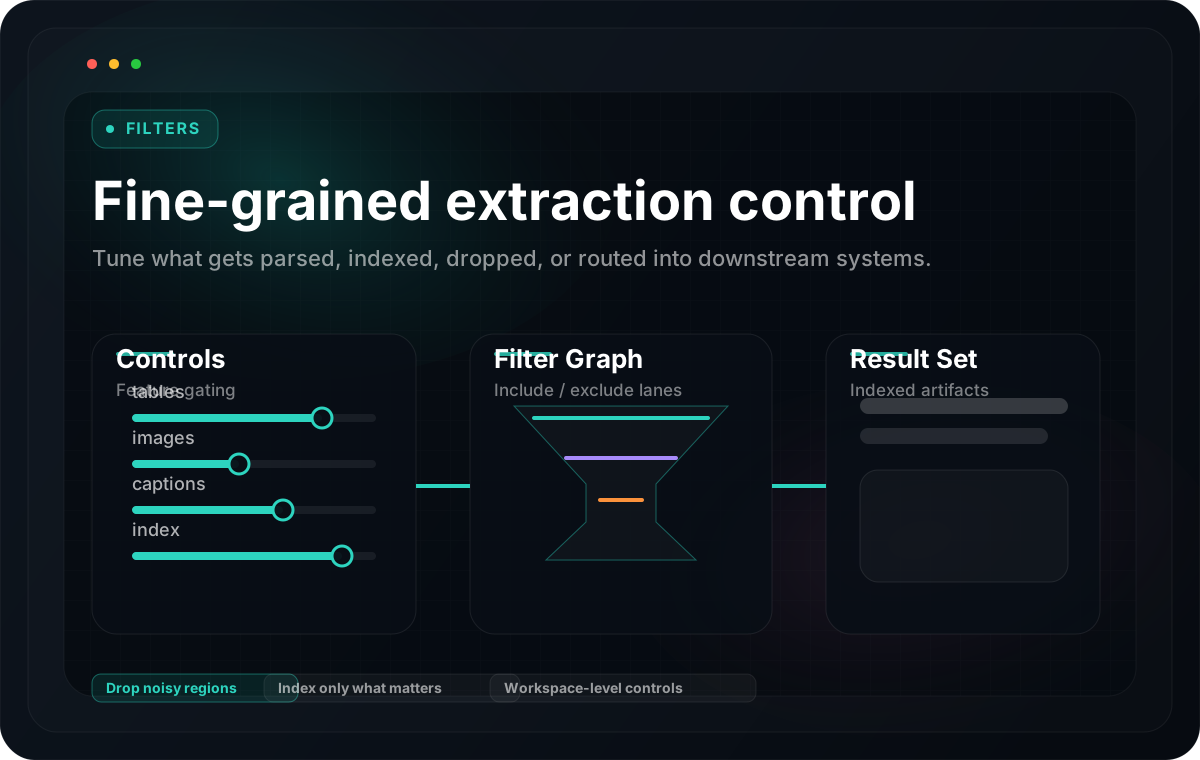
Search within a workspace and narrow results by document, filename, or tags.
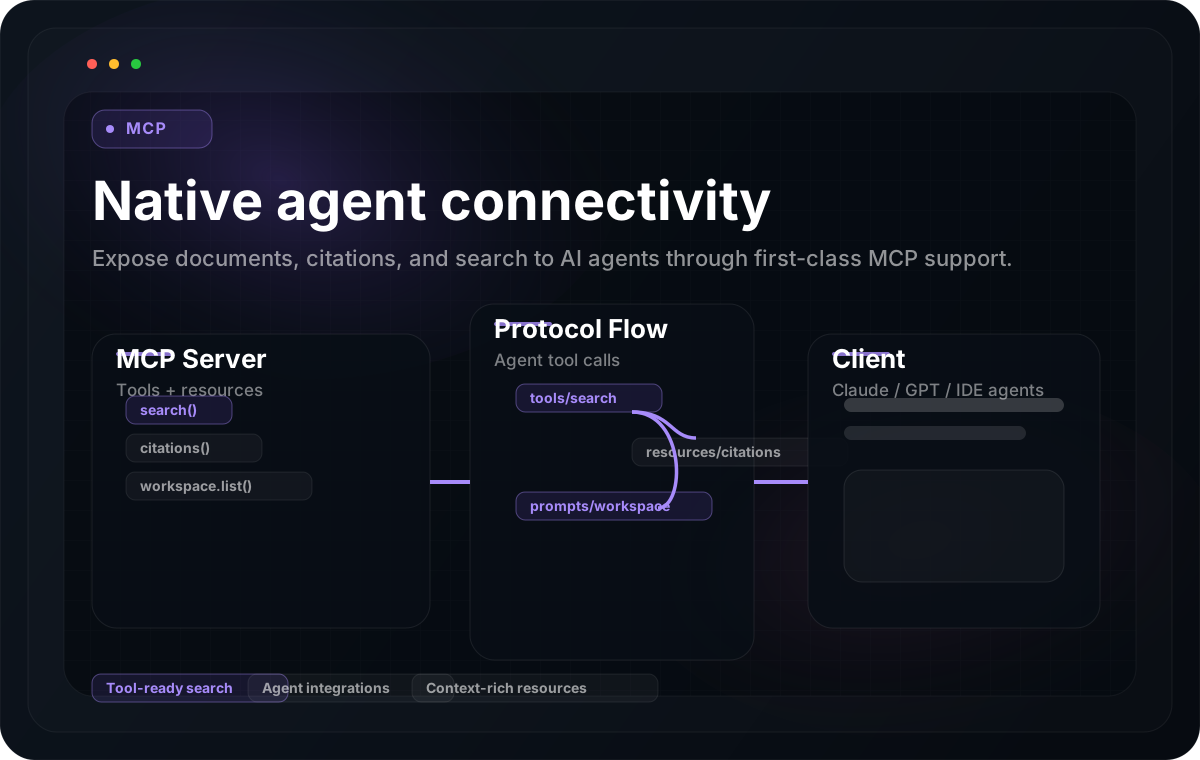
Authenticated REST tools for workspace search and grounded agent integrations.
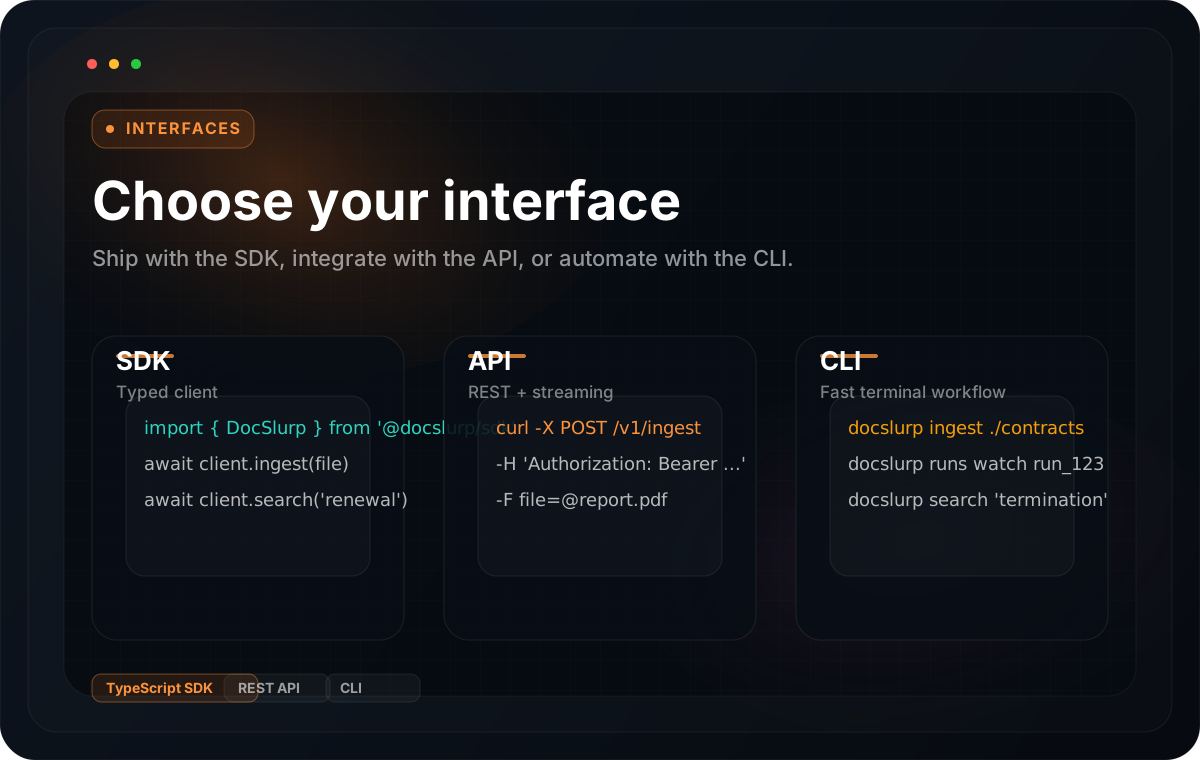
TypeScript SDK, REST API, and CLI — pick your interface, ship in minutes.
From upload to searchable documents, with sensible defaults.
Upload PDFs, DOCX, images, HTML — any document format.
LLM-powered extraction with smart model routing.
Entity extraction, classification, and relationship mapping.
Semantic search with citations, page images, and filters.
SDK for developers, REST for integrations, tools for AI agents — choose your path.
Upload, wait for processing, search, and ask questions with a small typed client.
import { createDocSlurpClient } from '@docslurp/sdk';

const client = createDocSlurpClient({
  apiUrl: process.env.DOCSLURP_URL!,
  apiKey: process.env.DOCSLURP_API_KEY,
});

const { results } = await client.search({
  workspaceId: 'workspace-id',
  q: 'revenue Q4',
});
for (const hit of results) {
  console.log(hit.text, hit.citation);
}Upload batches, track processing, and retrieve cited answers through REST.
curl -X POST "$DOCSLURP_URL/v1/ingest/bulk" \
  -H "Authorization: Bearer $DOCSLURP_API_KEY" \
  -F "[email protected]"

# Returns workspace, run, and documents.
# Check /v1/runs/<run-id>/progress
# before searching your workspace.Authenticated REST tools let your agents search the same workspace documents.
curl -X POST \
  "$DOCSLURP_URL/v1/mcp/tools/workspace.search" \
  -H "Authorization: Bearer $DOCSLURP_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"workspaceId":"workspace-id",
       "q":"revenue Q4"}'

# REST tools for agent integrations.Drop files, auto-create workspaces, and surface grounded search — no configuration required.